For most security-sensitive enterprises, the right posture is single-tenant VPC or full on-prem/air-gapped deployment depending on regulatory exposure, never shared multi-tenant infrastructure. The one non-negotiable control is runtime policy enforcement paired with tamper-resistant audit trails covering every prompt, retrieval, tool call, and response. The next section breaks down when each deployment model fits.
TL;DR:
- Operating a private LLM requires choosing the deployment model based on regulatory needs, latency, and staffing capabilities, with on-prem or air-gapped setups preferred for sensitive data.
- Hardware sizing must be aligned with model size, with models over 20 billion parameters demanding multi-GPU setups and thorough benchmarking to ensure performance meets workload demands.
- Runtime security involves strict container orchestration, network segmentation, signed images, and layered controls such as output validation and credential separation to prevent exploitation.
- Retrieval-augmented generation deployment must keep data and vector stores within the same security domain, with careful classification, ingestion isolation, and retention policies to avoid leaks.
- Achieving secure, compliant deployment involves a small, specialized team, phased rollout, comprehensive logging, and robust key management to prevent data breaches and ensure operational readiness.
Table of Contents
- Comparing on-prem, single-tenant VPC, and hybrid deployment models
- Infrastructure and sizing: GPUs, memory, storage, and latency planning
- Runtime architecture: containers, orchestration, and network segmentation
- RAG and data pipelines: keeping retrieval inside the security domain
- Security controls and runtime enforcement: applying OWASP guidance
- Governance, compliance, and lifecycle: aligning with NIST AI RMF
- Operational hardening: logging, monitoring, and incident response
- Implementation checklist and what a rollout actually takes
- Why sovereign deployments matter in high-consequence sectors
- How Forge AI supports a private deployment
- Sources
- FAQ
Comparing on-prem, single-tenant VPC, and hybrid deployment models
On-prem means the model, data, and compute stay entirely inside your own data center or air-gapped facility. Single-tenant VPC gives you dedicated cloud infrastructure with no resource sharing, offering similar isolation with less physical overhead. Hybrid splits the workload: sensitive inference stays local while less sensitive tasks (fine-tuning experiments, non-regulated workflows) run in managed cloud environments.
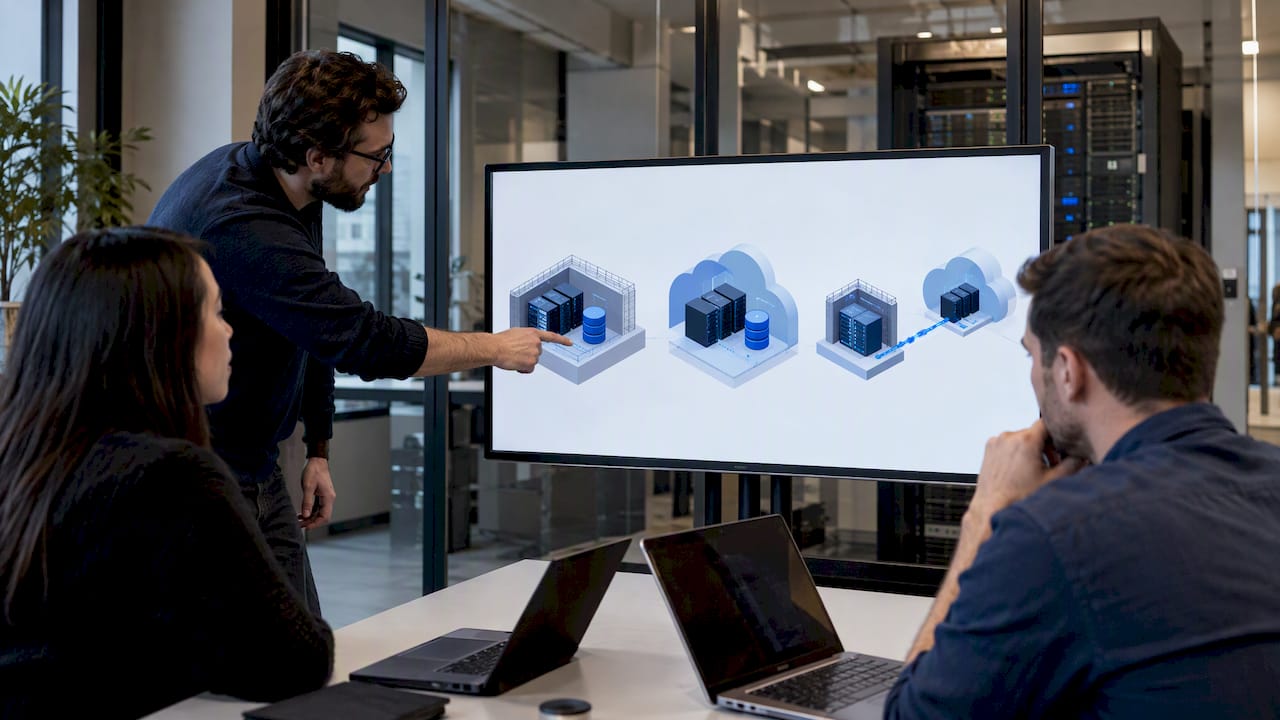
Each model trades privacy and control against operational burden. On-prem delivers the strongest data sovereignty but demands in-house hardware, cooling, and a team that can patch and monitor it around the clock. Single-tenant VPC reduces physical maintenance while preserving isolation, at the cost of a recurring cloud bill. Hybrid lowers infrastructure spend but expands your attack surface across two environments.
Three heuristics help narrow the choice:
- Regulatory sovereignty: defense, government, and financial workloads with strict data residency rules generally require on-prem or air-gapped deployment.
- Latency and scale: high-throughput consumer-facing workloads often fit single-tenant VPC better, since scaling GPU capacity is faster than procuring hardware.
- Staffing and cost: organizations without dedicated MLOps staff tend to underperform with on-prem unless they bring in outside integration support.
A defense contractor processing classified documents typically has no option but air-gapped. A logistics company running internal chat assistants for dispatch teams often does fine on single-tenant VPC.
Infrastructure and sizing: GPUs, memory, storage, and latency planning
Model size drives the hardware decision more than anything else. Models under 7 billion parameters can often run acceptably on CPU for low-throughput internal tools, though GPU inference is still faster. Mid-range models in the 7 to 20 billion parameter class generally need GPU acceleration to hit usable latency. Large models above 20 billion parameters require multi-GPU setups with enough VRAM to hold weights and KV-cache simultaneously.
Sizing heuristics worth planning around:
- VRAM: budget for model weights plus KV-cache headroom, which grows with context length and concurrent sessions.
- Embedding stores: vector database size scales with document count and embedding dimension, so plan disk and RAM around expected corpus growth.
- Disk and cache: fast NVMe storage for model checkpoints and vector indexes prevents I/O from becoming the bottleneck.
- Batching: larger batches raise throughput but increase per-request latency, a trade-off that must be tuned to the workload.
Benchmark before you commit hardware budget. Performance benchmarking guidance from TensorRT-LLM recommends measuring throughput and latency against representative datasets, and notes that configuration choices like KV-cache memory fraction and cuda graph settings materially change results. Collect throughput, p95 latency, and out-of-memory frequency during load tests, not just average latency, since averages hide the spikes that break production SLAs.
Runtime architecture: containers, orchestration, and network segmentation
Containers generally beat VMs for LLM workloads because they patch faster and support signed, versioned image supply chains. VMs still make sense for air-gapped sites with strict physical isolation requirements or legacy compliance mandates that demand full OS-level separation.
- Choose orchestration to match scale and isolation needs. Kubernetes with namespace isolation and network policies suits multi-team enterprise deployments; single-tenant VPC appliances work for dedicated cloud instances; simple Docker Compose stacks are often sufficient for air-gapped sites with a single workload.
- Segment networks by function. Keep frontend traffic, inference services, and the vector database on separate network segments with a reverse proxy and firewall rules mediating access between them.
- Verify image provenance before deployment. Require signed container images and run automated CVE scanning on every build, not just at initial deployment.
- Separate ingestion from inference. Self-hosted RAG stack documentation shows containerized components, Nginx, RAG backend, local LLM runtime, vector database, and caches, running on separated Docker networks, with installation scripts that auto-detect GPU versus CPU hardware to configure the right mode.
This separation limits blast radius: a compromised frontend container should never have a network path directly to the model weights or vector store.
RAG and data pipelines: keeping retrieval inside the security domain
Retrieval-augmented generation multiplies your data surface if it is not architected carefully. The vector store and its metadata need to live inside the same security domain as the model itself, not in a separate managed service with different access controls.
- Classify before embedding. Strip or mask sensitive fields at ingestion time rather than relying on retrieval-time filtering, since embeddings themselves can leak information.
- Isolate ingestion workloads. Operational guidance from self-hosted RAG deployments recommends separating embedding generation into dedicated worker pools with their own quotas, so high-volume document ingestion cannot starve inference GPU capacity.
- Set retention and deletion policies. Align reindexing schedules and erasure procedures with your broader data governance rules, including right-to-erasure requests.
- Plan for key management. Encrypting vector stores introduces a key encryption key dependency that needs its own recovery plan, covered in more detail below.
A RAG pipeline that skips data classification turns your retrieval layer into an unmonitored copy of your most sensitive records.
Security controls and runtime enforcement: applying OWASP guidance
Model outputs, retrieval results, and tool-call arguments all need treatment as sensitive data requiring validation before they reach a user or downstream system. OWASP’s Top 10 for LLM Applications prescribes layered runtime controls: strict output schemas, prompt sanitization, least-privilege tool mediation, modality filtering, and character-strip defenses against invisible-character injection attacks.
Concrete controls to put in production:
- Define output schemas and validate in application code. Never trust a model response to be well-formed; parse and validate it against a strict schema before acting on it.
- Keep credentials outside the model. Tool calls that trigger state changes should route through a deterministic policy decision point that holds credentials and enforces least privilege, never the model itself.
- Strip invisible characters at ingest and render boundaries. OWASP guidance flags zero-width characters and variation selectors as a known exfiltration vector that needs explicit stripping.
- Layer modality filters. Apply sanitization to every input type your system accepts, not just plain text prompts.
Pro Tip: Route every tool call through a centralized policy decision point rather than embedding permission logic in each integration; it makes audit logging consistent across heterogeneous model runtimes.
Governance, compliance, and lifecycle: aligning with NIST AI RMF
The NIST AI Risk Management Framework’s Generative AI Profile adds twelve generative-AI-specific risks and maps suggested actions to the framework’s Govern, Map, Measure, and Manage functions, including pre-deployment testing thresholds and inventory requirements.
- Maintain a living AI system inventory. Track model versions, data lineage, and named human oversight roles for every deployed system.
- Gate deployment with measurable thresholds. Use the profile’s suggested actions to define go/no-go criteria before a model reaches production.
- Plan decommissioning up front. The Generative AI Profile calls out decommissioning and inventory management as necessary to avoid orphaned models and forgotten data stores.
- Address third-party components contractually. Any vendor-supplied model, library, or hosting layer needs SLA terms covering patching, breach notification, and data handling.
Treat the framework as a set of lifecycle functions tied to concrete deployment gates, not a one-time compliance checklist.
Operational hardening: logging, monitoring, and incident response
Runtime enforcement, not design-time policy documents, is the part of secure LLM deployment that gets skipped most often. Audit trails need to cover prompts, retrieval traces, tool calls, and final responses to be governance-ready, and the strongest implementations add cryptographic integrity to prevent tampering after the fact.
- Log every stage of the request lifecycle. Prompt, retrieval trace, tool call, and response each need a timestamped, tamper-evident record.
- Define alerting rules for anomalous patterns. Watch for exfiltration-shaped queries, unusually high-rate retrieval, and abnormal tool invocation, and write SRE runbooks for each alert type.
- Automate supply-chain scanning. Run CVE scans against container images and model artifacts on a recurring schedule, not just at build time.
- Externalize key management. Operational notes on RAG deployments warn that key encryption key mismanagement can permanently lock encrypted vector stores, and recommend storing KEK recovery procedures in an enterprise KMS with regular recovery drills rather than application-local key files.
A KEK stored only in application config is a single point of failure that can brick your entire retrieval layer during a routine credential rotation.
Implementation checklist and what a rollout actually takes
A private LLM deployment needs a small, specific team: a security architect, an infrastructure engineer, an MLOps specialist, a data steward, and an SRE for ongoing operations. Skipping any of these roles tends to surface as a gap later, usually around audit logging or key recovery.
- Phase the rollout. Move from proof of concept to a limited pilot, then staged production, then full monitoring coverage, rather than deploying broadly on day one.
- Budget for four cost drivers. GPU infrastructure hours, model licensing where applicable, integration engineering effort, and ongoing operations are the recurring line items.
- Watch for common red flags. Missing system inventory, no runtime policy enforcement, and no tested key-recovery plan are the three most common gaps found during pre-production review.
- Size the timeline realistically. A pilot can move in weeks; a hardened, audited production deployment with full monitoring typically takes longer, driven mostly by integration and governance sign-off, not model training.
Why sovereign deployments matter in high-consequence sectors
Twenty years spent securing sensitive operations teaches you that the failure mode is rarely the model. It’s the missing runtime policy, the untested key recovery plan, the vector store nobody classified. Air-gapped and single-tenant designs earn their keep in finance, defense, and energy because they remove entire categories of exfiltration risk by design. In practice, that means externalized key management, strict indexing policy before anything gets embedded, and a runtime policy decision point mediating every tool call.
— John Ezzell, Founder
How Forge AI supports a private deployment
Every control in this guide, from air-gapped infrastructure to runtime policy enforcement, maps to specific private AI deployment services rather than a generic promise.
- Secure local and air-gapped deployment builds infrastructure designed to keep data within your environment.
- Custom model integration and optimization tunes performance aiming to avoid cloud dependence.
- Sovereign MLOps and runtime orchestration support policy enforcement and audit logging as recommended in this guide.
The outcome sought is that data, models, and domain intelligence stay inside your own infrastructure, validated for privacy and auditability. If your team is scoping a deployment, review Forge AI’s solutions to start the conversation.
Sources
The recommendations above draw on published frameworks and practitioner documentation rather than vendor marketing.
- Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile
- OWASP Top 10 for LLM Applications 2026
- TensorRT-LLM performance overview
FAQ
Is there any private LLM available for enterprise use?
Yes, several open-weight and licensed models can run entirely inside enterprise infrastructure rather than through a public API. The right choice depends on your hardware, data sensitivity, and whether the model’s license permits internal fine-tuning.
Can I host my own LLM model in-house?
Yes, self-hosting is a well-established pattern, with containerized stacks running the model runtime, vector database, and supporting services inside your own network. Hardware requirements scale with model size, so a 7 billion parameter model has very different needs than a 20-plus billion parameter one.
How do I set up a private LLM deployment step by step?
Start by choosing a deployment model (on-prem, single-tenant VPC, or hybrid), then size hardware to your model and expected load, then build the runtime with network segmentation between frontend, inference, and data layers. Layer in runtime policy enforcement and audit logging from day one rather than adding them after launch.
Is a local LLM really private if it runs on my own hardware?
Running a model locally removes the risk of your prompts and data leaving your infrastructure through a third-party API, which addresses the biggest exposure. It is not automatically private in a governance sense: you still need access controls, audit logging, and data classification in your RAG pipeline to prevent internal exposure or misconfigured retrieval.